Getting the transcript
Reading the captions from YouTube. A video nobody has opened here before takes 10 to 30 seconds; this page fills in on its own.
Getting the transcript
Reading the captions from YouTube. A video nobody has opened here before takes 10 to 30 seconds; this page fills in on its own.
AI Engineer · @aiDotEngineer
This video has no Most replayed graph yet: YouTube shows one only once a video has enough views. These are the moments viewers replayed most in AI Engineer's most watched videos.
Most replayed moment at 18:45
4.8x that video's typical replay level
that they're they're changing they're changing things in the database not yet. You want to run them through the ontology first and make sure that works. Okay. I only got an I've got I've got another I've just a short time. I'm going to try to show you some of the things that um that you can
Said at 18:37
Most replayed moment at 16:13
3.6x that video's typical replay level
method signatures, the program layout and the call stacks. So here's some examples. I don't think you'll be able to read this one, but this is like the level of abstraction we're at. It's how we're actually going to lay this stuff out and how these systems are going to interact. Dylan Mulroy from Cloudflare talks a
Said at 16:06
Most replayed moment at 6:57
5.9x that video's typical replay level
do light mode. It's I It's not my nature, but sometimes. That's better, yeah? Okay. So we have we have a model and we're trying an old LG Sorry. We We shouldn't have seen that. No, we'll
Said at 6:50
The graph counts replays. It does not show where viewers stopped watching.
Words
1,917
Runtime
13:04
Speaking pace
147wpm
Reading time
8min
147 words per minute, below the 160 25th percentile of 349 measured videos. That distribution comes from the 349-video hook study.
Opening (first 30 seconds)
[music] Hello, welcome. Uh, this is a big room, so you're if you're in the back, don't hesitate to come closer. Um, my name is Stefania Dug. I'm a research scientist at Sakana AI in Tokyo. Uh I used to be based here and AI engineering uh is home community for me before being the hyperloop. So it's very good to be back and today I'm going to talk to you about memory harnesses
74 words, the words spoken in the first 30 seconds at 147 words per minute.
Free, no signup. See how the first 30 seconds hold attention, with rewrites.
Sentence shape
| Measure | This transcript |
|---|---|
| Sentences | 99 |
| Average words per sentence | 19.4 |
| Longest sentence | 114 words |
| Questions asked | 12 |
| Sentences containing a number | 11 |
Most used terms
Filler phrases
95 in total: like 27 · uh 25 · um 24 · actually 11 · right? 5 · kind of 2 · basically 1.
A literal whole-word count of the same phrase list the Prepublish browser extension uses, so a phrase inside another word is not counted and a phrase used in its ordinary sense still is. It is a count and not a judgement.
What this transcript is
Every word below is the caption track YouTube publishes for this video, pulled from the video itself and reproduced unchanged. It is not Prepublish's writing, not a summary, and not a re-transcription: it is the video's own published captions. English captions, generated automatically by YouTube, in the video’s original language. Source: the video on YouTube. A channel that would rather this page did not exist can ask for its removal through the contact page, and it is removed.
[music] Hello, welcome. Uh, this is a big room, so you're if you're in the back, don't hesitate to come closer. Um, my name is Stefania Dug. I'm a research scientist at Sakana AI in Tokyo. Uh I used to be based here and AI engineering uh is home community for me before being the hyperloop. So it's very good to be back and today I'm going to talk to you about memory harnesses for longunning research agents on device. So if you work with long horizon tasks, you probably run into this issue of context blow, right?
Like when the model starts contradicting itself or it has to redo the work because it forgot it did that task in the first place or it starts to drift from your questions because it forgot them. And this this matters now more than ever because from this recent projections from meter we see that the trend is to solve longer and longer uh horizon tasks and also that we're getting fewer and fewer model releases. So at some point later this year we're going to have this convergence right where we'll get many more long-term horizon tasks and fewer model releases.
So that makes this issue of dealing with context rot a priority. And why did I wanted to to tackle this problem on local models and with a local harness? Uh maybe some of you have seen this tweet. It's only two days old. Uh the CEO of Coinbase actually shared how their company managed to reduce their AI spent while actually increasing uh the AI usage. And the way they did that was by transitioning to use many more local models but also having better practices like using better routing, better caching, keeping the context clean and then having better visibility for what people are using and for what uh what kind of task.
So we are seeing the local models like crossing the line, right? Like GLM is on everyone's minds like especially with Fable going away. uh DeepSync V4 flash can now be run on uh M3 Ultra and there's still a bottleneck for RAM. It's tricky, but these local models are starting to be useful for agentic tasks and for tool use. So, I wanted to show you what has been my setup for the experiments I'm going to share with you today.
Uh this this is my Mac. It's still running evaluations right now uh back in my desk in Tokyo and I'm controlling it from my phone. Um and after running EVAs non-stop for a couple of days, it started to get hot. So I had my husband put fans around it. Um we're running out of fans, but the the machine is still running and the valves are still giving results. Um, on this M3 Ultra with 96 gigabytes and 28 core CPUs, I'm using two models.
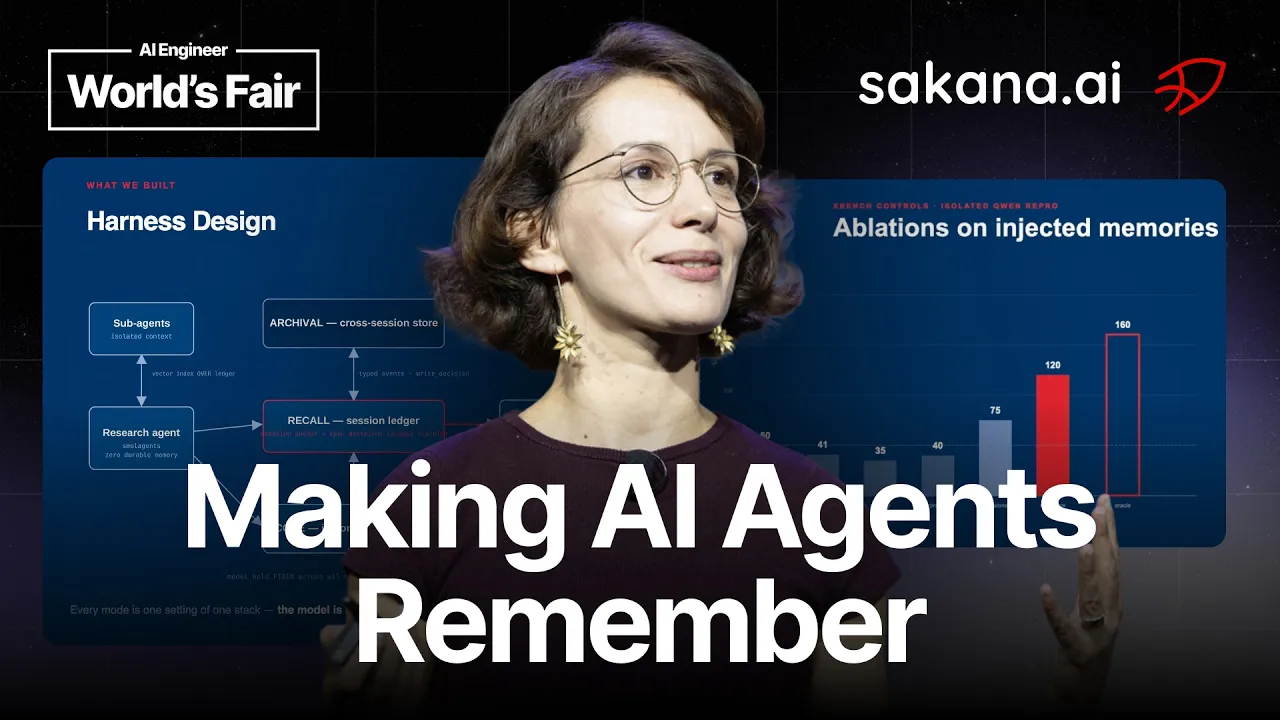
I'm using a Quen 27B quantise at 4 and the DC V4 flash. And before I show you how I built the memory harness on this machine, I wanted to tell you what this little what is this an example of, right? like memory when we design a harness for memory this is the mental model I want you to have in mind um you can think of memory as a write manage read loop so it's not just the database store it's actually this control loop around the model more concretely how did I take that loop and customized it so this is my harness design like I started with research agents that are the small agents because they have zero durable memory and I wanted all the memory to come from the harness And then um in the middle I have a core which is always shown to to the agent um of traces.
And then I have a recall block where I'm testing different modes and an archival block where I'm keep keeping track of information across different um sessions. And in that recall block I'm actually going through a ladder of modes that I'm testing. The baseline is like not to use memory at all. no recall at all. So I'm I'm testing for that. Uh next is to use rag vector vector rag um just to see whatever like the harness would pull in terms of similarity.
Then is to use a decisions uh ledger where I actually keep track of what decisions are being made for every turn and then I can prioritize them. And last but not least and this piece is very important. I have a what I call an oracle, but basically this is the ground truth. So this is like telling the harness for every loop what the correct memory that needs to be retrieved is. And the model is fixed across all the different tasks.
So the only things that I'm changing is like these different variables in the recall block. And I wanted to to give you an example of a first task that I tested. So I wanted to see if I give the agent a task of doing literature review and I'm including a lot of papers in the corpus where there was a big scientific claim like this is actually a nature paper where they said they discovered 742,000 promising materials like it was a very big claim which got retracted later but the retraction it's a much smaller like haystack back needle in that corpus than the headlines and the citations.
So I wanted to see if if the system can retrieve the right answer for these type of questions. And what I found was because like for these tasks all the papers and all the information fit into the context the memory actually didn't add more capability. It was the same performance with memory and without memory and it only added more cost. So when your task fits in context, the harness doesn't add much. However, if I start to run tasks that are longer term horizon and the entire task and the relevant context doesn't uh fit, then having a good memory harness really starts to pay off.
So this is another example of a task that I ran. This is actually from an established benchmark for a long horizon uh tasks memory. It's called Xbench. And this is an example of a question, right? So I'm asking a question and then like the right answer is in a like step 124. But the moment when I ask the question, I'm asking it like at step 500. So it's completely outside of the context window and the model needs to use the memory harness to retrieve the specific answer from the right step.
So I'm testing this by uh changing the different policy ladder that I explained before with memory off uh by deploying recall different types of recall and by using the oracle as a reference. And what I found was that with the ranked recall, the model gets the right answer um more frequently than without. And here is a breakdown of the decomposition of performance on this Xbench tasks. So I ran over uh 68 questions and for each of these questions there were like multiple um cells and lots of different seeds.
And what I found was that the rank only ledger performed the best and it performed better than like just gating the harness by saying do you need to use memory or do you not need to use memory and you're probably going to ask like why is the oracle not hitting like the max and I'm going to explain that too. So the oracle what it does it provides the right information the right memory to the model but it doesn't force it to use it.
So the model can get the right memory but still retrieve the wrong information or choose to ignore it or be confused. So that's why the oracle in this case doesn't hit the max performance. And I've done lots of ablations on these tasks to see like what happens if I give arbitrary um examples. What happens if I give it the wrong step? What happens if I give it the most recent step? And I still found that the best performing condition was the one with the ranked policy for recall.
And this actually works on several models, not only on the Quen 27B, but also on the DS4 flash. And it also works across different benchmarks. I also tried it on the Spider V2 benchmark. And it's not just that it gives you better recall, it actually costs less. So maybe a good heristic to have here is that bad memory is expensive because it spends more token and it can send agent the wrong way. But having like a good structural policy for recall can save you a lot of tokens and uh budget.
So one thing that I want to encourage you from this experiment is to consider the recall policy as a first class metric and to start to think about how you might use it in your systems. Like what are the type of memories that you want to store? What how do you rank them? Like how do you design your recall function? And then um what are the type what survives when you run this over and over and over? and um multiple sessions, multiple runs and this is just a simple first kind of experiment.
Um but the memory technique landscape is very rich. Um so there's over 30 runnable cookbooks that are shared in this open-source repository from um Diamond and memory is complex. We have short-term long-term different cognitive techniques. uh we can use start to use evaluation results as well. Um and right now there's actually a a pretty broad landscape of solutions, right? So going from simple file system retrieval to training memory models.
Um there's there's a wide spectrum of solutions from less structural to completely structured. Um so I think there's a lot of research we're going to see in this space. uh it's important and it becomes more and more relevant and for me it's been super fun to to test this on local models um because I got to control everything. I got to control the data I was using the entire traces of compute and evaluations and um yeah I I see that as an example of sovereignty and it comes at a cost.
Uh I didn't tell you that these local models I can only what uh run them in serial like they don't support batch querying for the DeepSc V4 flash. So that's why I am still running evaluations back on my computer in Tokyo or I I was doing it on the flight on my way here because it takes a long time. Um, but I still think it's very powerful and it's a very good test for what memory can do when you can control every single step of the pipeline.
And this sovereign capability is part of a bigger ecosystem that is very important for us at Sakanai in Japan. Um, we believe in the importance of sovereign AI today more than ever. And we are also hiring. So, if you're interested and want to hear more about this and if you want to come join us in Japan, come talk to me. Uh, thank you very much. [applause]
The words are the caption track's own and nothing is reworded or re-transcribed. Paragraph breaks are placed between sentences so the text reads as prose.
Free tools for your own script. No signup, no login.
Paste your draft and see where viewers are likely to drop off, with a rewrite for each weak line.
Paste the first 30 seconds of your own draft for a hook score and rewrites.
Check your draft against YouTube's advertiser-friendly guidelines before you record it.
Read this channel's public videos and transcripts, and download a writing brief for it.