Getting the transcript
Reading the captions from YouTube. A video nobody has opened here before takes 10 to 30 seconds; this page fills in on its own.
Getting the transcript
Reading the captions from YouTube. A video nobody has opened here before takes 10 to 30 seconds; this page fills in on its own.
AI Engineer · @aiDotEngineer
This video has no Most replayed graph yet: YouTube shows one only once a video has enough views. These are the moments viewers replayed most in AI Engineer's most watched videos.
Most replayed moment at 11:58
4.6x that video's typical replay level
issues. Uh I also invented OS certification. I just close the tracker whenever I want, so I have my life back. So, does this work? Yes, sort of. >> [laughter] >> Which leads me to act three, slow the down. Everything's broken.
Said at 11:52
Most replayed moment at 18:45
4.8x that video's typical replay level
that they're they're changing they're changing things in the database not yet. You want to run them through the ontology first and make sure that works. Okay. I only got an I've got I've got another I've just a short time. I'm going to try to show you some of the things that um that you can
Said at 18:37
Most replayed moment at 16:13
3.6x that video's typical replay level
method signatures, the program layout and the call stacks. So here's some examples. I don't think you'll be able to read this one, but this is like the level of abstraction we're at. It's how we're actually going to lay this stuff out and how these systems are going to interact. Dylan Mulroy from Cloudflare talks a
Said at 16:06
The graph counts replays. It does not show where viewers stopped watching.
Words
1,226
Runtime
8:42
Speaking pace
141wpm
Reading time
5min
141 words per minute, below the 160 25th percentile of 349 measured videos. That distribution comes from the 349-video hook study.
Opening (first 30 seconds)
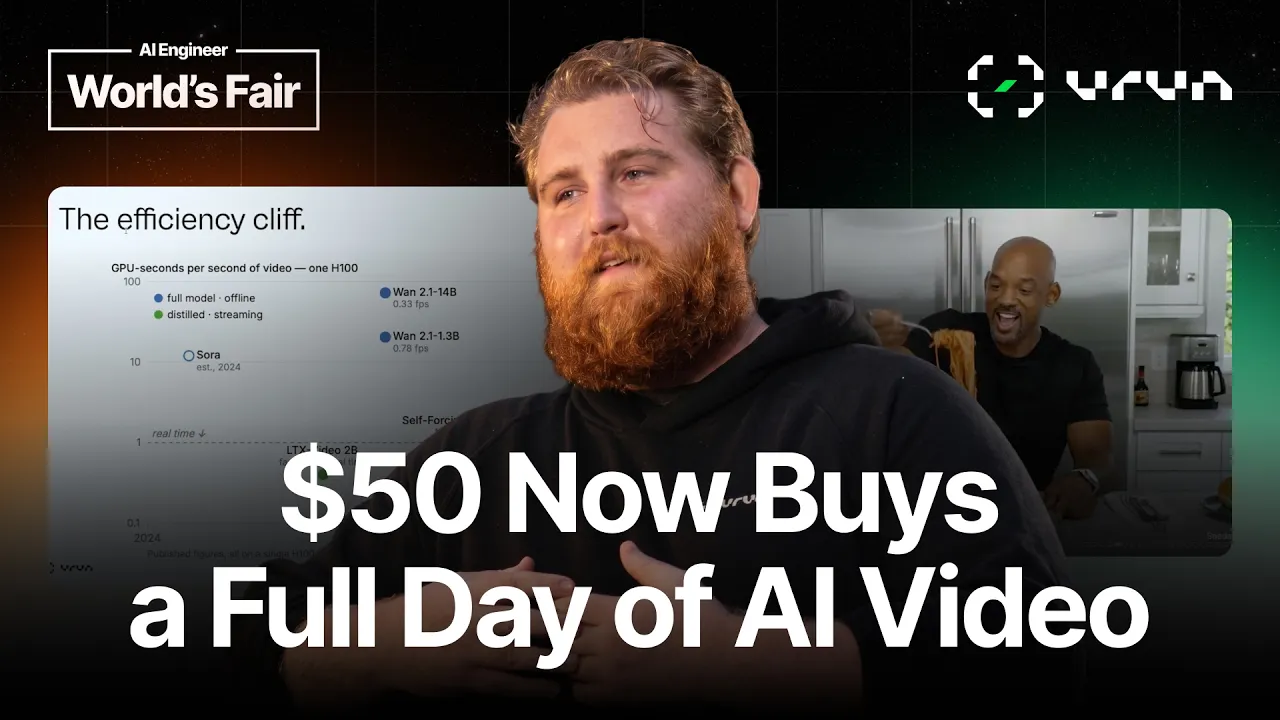
[music] >> I am Keegan. I'm the founder of U Run, um, a new kind of inference provider focused around, uh, interactive media. And I'm here to talk about generative video. So, we hear a lot about generative video improving along the quality axis at the frontier. We have the classic Will Smith eating spaghetti from 2023. It is nightmare fuel and not something you would ever mistake for reality. In
71 words, the words spoken in the first 30 seconds at 141 words per minute.
Free, no signup. See how the first 30 seconds hold attention, with rewrites.
Sentence shape
| Measure | This transcript |
|---|---|
| Sentences | 64 |
| Average words per sentence | 19.2 |
| Longest sentence | 50 words |
| Questions asked | 2 |
| Sentences containing a number | 11 |
Most used terms
Filler phrases
41 in total: um 15 · like 8 · uh 7 · actually 5 · kind of 3 · you know 3.
A literal whole-word count of the same phrase list the Prepublish browser extension uses, so a phrase inside another word is not counted and a phrase used in its ordinary sense still is. It is a count and not a judgement.
What this transcript is
Every word below is the caption track YouTube publishes for this video, pulled from the video itself and reproduced unchanged. It is not Prepublish's writing, not a summary, and not a re-transcription: it is the video's own published captions. English captions, generated automatically by YouTube, in the video’s original language. Source: the video on YouTube. A channel that would rather this page did not exist can ask for its removal through the contact page, and it is removed.
[music] >> I am Keegan. I'm the founder of U Run, um, a new kind of inference provider focused around, uh, interactive media. And I'm here to talk about generative video. So, we hear a lot about generative video improving along the quality axis at the frontier. We have the classic Will Smith eating spaghetti from 2023. It is nightmare fuel and not something you would ever mistake for reality. In 2024, we got Sora and it gets a little better.
It still has a bit of, you know, an AI feel to it, but it it's getting there. And Sora 2, you know, even better. But SeeDance this year, um, absolutely incredible. So photorealistic. And it's it's no wonder that we talk a lot about quality, but I'm here to talk about another axis which models are improving along, which is efficiency and, uh, the long horizon generations. So, what you're watching here is a demo for a model called Helios that we serve at U Run.
Um, the generation in the bottom right corner, you'll see, is a long continuous generation. And the other video, um, is a bunch of clips, um, that have been generated faster than you can consume them. Uh, and they're about at the same quality as the frontier models were last year. They're Helios is a distill of Juan 2.1 14B. Um, and I'll talk a bit about the techniques that are used in the various models that are hitting the scene right now, but there's been an explosion in just the last year uh, terms of efficiency and capabilities.
Um so like looking at this, I kind of ruined it with the last club, but you can guess which one is real time and which one was generated in a number of minutes. And the one on the right is and arguably a bit better. It's got better motion and it was generated for about a 100th of the cost. And these are just some of the charts showing the quality bar for both long and short video generation. Helios came out in March and it's it's pretty incredible to see how fast these are improving.
But these are techniques that are being applied all over the place, not just the one model. There's world models which can keep consistency over long horizons and you can control in a fine-grained way, the camera and the viewport. There's avatar models like we just talked about with lemon slice and there's video-to-video models that can can transform what you're seeing in in real time, almost like a magic mirror. There's actually been an explosion of innovation.
There's been at least 40 models with real-time capabilities and long horizon generation capabilities released this year. Show of hands, who here has burned 10 or even $50 worth of tokens in an hour with Clockwork? A lot of people. And so we're at a place right now where $10 can get you 3 hours worth of generated video continuously with most of these models and $50 would give you an entire day interacting with an AI in a visual medium. 15 hours.
And so I want to talk a little bit about the different things this enables in terms of the way that we interact with computers. Um and I'll talk a little bit about what we're doing at You Run to try and make it easier for folks to experiment and build out applications like this. So, one such use case would be a magic mirror. You [snorts] could have your webcam and you could ask to see yourself in any outfit. You could ask to see yourself in a car you like or with a haircut you're considering.
Um a lot of different possibilities because these are open-ended models that can transform what they're seeing on a webcam in real time. I also think about accessibility a lot with these models. Um you know, working with AI involves a lot of reading and a lot of text. For some people that's more difficult. Um for some people they just don't think in in text. They think visually and learn better that way. Uh so, there's more opportunities to have companions or visual mediums that are going to allow more people to experience the things a lot of us have with coding models.
And I'm excited about content creation. Um so far we've very much had a slot machine type approach where you're setting up a prompt and maybe some key frames and spending about $10 a minute to try and get the shot that you want. But with these models you can actually steer them in real time in under a second while they're generating and get the actual shots that you want. Maybe you're piloting an agent that you're able to look over its shoulder and see what it's generating in real time.
Um but you're able to more granularly control the content you're generating and with modern models like Google Gemini Omni, you can actually render these out as a more full fidelity clip. And of course, we all are thinking about world models, but I want to take the the focus off of just kind of the the the basic world models that we talk a lot about and just try to expand the horizons of what we can do with this technology.
And so, what does it look like to actually build an application like this? So, you're going to need GPUs all over the world potentially if you've got a global audience that's going to be using these. You're going to need to think [snorts] about where you're connecting the users to, what GPUs you're going to use to serve them. You're going to need to set up probably WebRTC and ICE and TURN. And for the most interesting use cases, you're going to want a model wire multiple models together in continuous streaming workflows.
Building those real-time harnesses, and you're going to want things synchronized with your controls that you're providing to your end users with every frame and continually providing a smooth streaming experience. And so, our idea is what if there was just a React component that you could drop into your application to make it easy to provide video interactively inside your applications with any model. And behind the scenes, there's a programmable Python runtime that lets you easily build these complex pipelines generating asynchronously so that you can build avatar models, you can build these video-to-video transformation models, you can experiment and and build whatever you can really imagine on top of these.
And I argue that in 2026, don't just need platforms, we need software factories and ways for agents interact with these. And so we've actually built one that will let folks hook into a CLI or an MCP server and build these kinds of applications. >> [gasps and sighs] >> And so the models are here and the frontier is really in how we serve them. Uh I went way over I went way under time. Um >> [laughter] >> but we are looking for design partners who want to push the boundaries of human human-computer interaction and we're hiring at YURUN.
Um so come see me after the talk if uh if you're interested in chatting more.
The words are the caption track's own and nothing is reworded or re-transcribed. Paragraph breaks are placed between sentences so the text reads as prose.
Free tools for your own script. No signup, no login.
Paste your draft and see where viewers are likely to drop off, with a rewrite for each weak line.
Paste the first 30 seconds of your own draft for a hook score and rewrites.
Check your draft against YouTube's advertiser-friendly guidelines before you record it.
Read this channel's public videos and transcripts, and download a writing brief for it.