Getting the transcript
Reading the captions from YouTube. A video nobody has opened here before takes 10 to 30 seconds; this page fills in on its own.
Getting the transcript
Reading the captions from YouTube. A video nobody has opened here before takes 10 to 30 seconds; this page fills in on its own.
AI Engineer · @aiDotEngineer
This video has no Most replayed graph yet: YouTube shows one only once a video has enough views. These are the moments viewers replayed most in AI Engineer's most watched videos.
Most replayed moment at 18:45
4.8x that video's typical replay level
that they're they're changing they're changing things in the database not yet. You want to run them through the ontology first and make sure that works. Okay. I only got an I've got I've got another I've just a short time. I'm going to try to show you some of the things that um that you can
Said at 18:37
Most replayed moment at 16:13
3.6x that video's typical replay level
method signatures, the program layout and the call stacks. So here's some examples. I don't think you'll be able to read this one, but this is like the level of abstraction we're at. It's how we're actually going to lay this stuff out and how these systems are going to interact. Dylan Mulroy from Cloudflare talks a
Said at 16:06
Most replayed moment at 6:57
5.9x that video's typical replay level
do light mode. It's I It's not my nature, but sometimes. That's better, yeah? Okay. So we have we have a model and we're trying an old LG Sorry. We We shouldn't have seen that. No, we'll
Said at 6:50
The graph counts replays. It does not show where viewers stopped watching.
Words
1,796
Runtime
16:16
Speaking pace
110wpm
Reading time
7min
110 words per minute, below the 160 25th percentile of 349 measured videos. That distribution comes from the 349-video hook study.
Opening (first 30 seconds)
[music] This April, OBI ran a hiring challenge, a competition called Parameter Golf. The top contributor was one candidate that they couldn't hire. It wasn't a person, it's an agent we build called Aiden. In parameter golf, the goal is to train the best language model you can under size and computation constraints. About 1,000
55 words, the words spoken in the first 30 seconds at 110 words per minute.
Free, no signup. See how the first 30 seconds hold attention, with rewrites.
Sentence shape
| Measure | This transcript |
|---|---|
| Sentences | 123 |
| Average words per sentence | 14.6 |
| Longest sentence | 62 words |
| Questions asked | 2 |
| Sentences containing a number | 12 |
Most used terms
Filler phrases
33 in total: like 10 · actually 8 · um 8 · uh 6 · I mean 1.
A literal whole-word count of the same phrase list the Prepublish browser extension uses, so a phrase inside another word is not counted and a phrase used in its ordinary sense still is. It is a count and not a judgement.
What this transcript is
Every word below is the caption track YouTube publishes for this video, pulled from the video itself and reproduced unchanged. It is not Prepublish's writing, not a summary, and not a re-transcription: it is the video's own published captions. English captions, generated automatically by YouTube, in the video’s original language. Source: the video on YouTube. A channel that would rather this page did not exist can ask for its removal through the contact page, and it is removed.
[music] This April, OBI ran a hiring challenge, a competition called Parameter Golf. The top contributor was one candidate that they couldn't hire. It wasn't a person, it's an agent we build called Aiden. In parameter golf, the goal is to train the best language model you can under size and computation constraints. About 1,000 machine learning engineers, researchers participate. They fired 2,000 submissions. Only 47 passed open review and made into the leaderboard.
Seven of those are actually agents. More than twice what any human contributed. You've seen a lot of auto research today. Agents are here climbing benchmarks. Those are really impressive results. The question I want to ask is a bit different here. Can the auto research agent produce work that a human community actually recognize beyond a good score agent is optimizing for something that other engineers can merge fork and build on.
So instead of having an agent just here climbing locally, we build one that publishes its own work and that's Aiden. Quick context on us. Wiko is a auto research company that founded about two and a half years ago. Uh I'm co-founder and a CEO Jungao. Um got my PhD at UCR on reinforcement learning. About two years ago, we buil aid the top auto research agent independently evaluated by OpenAI in their MLE bench paper. Even though back then there's a no such name called auto research, people call it machine learning engineering agent.
Aiden is the next step and a experimental prototype. It's a multi-agent self-improving system that can read public information like research papers and other PRs, run its own experiments and submit a PR once the findings pass a quality gate. We send Aiden to parameter golf competition and it ran for about 22 days. By the end, Aid has set seven leaderboard records. Each one is a new best for the competition stampled by OpenAI and the best human only made three.
Passing the host review is a one signal for the quality. A second maybe more important one is whether other participants would build on your work. And it turns out Aiden's work had the highest impact within the whole community. Here we are using a inference measure that used widely in academia. It's called a H index. Roughly if you have X papers get cited X times then your Ach index is X. Computed over PRs. Aiden was 10 and the next human was seven.
The whole community was building on a AI systems work including many of other leaderboard entries. To break it down a little bit, why can a autonomous AI system be so powerful? One obvious reason is that it's an AI. It can run tirelessly. Over 22 days, it ran about 1,300 experiments on a single H100 node. But the throughput isn't the whole picture. A well tuned AI system can also keep its output quality high. On the compute side, it uses at most 4% of competition's total compute. and it made about 15% of the records.
Also, 28% of its submissions made the leaderboard. Roughly six times higher heat rate than the community average. So, Aiden actually lifted the signal noise ratio within the whole community's public communication channel, which is a PR. It didn't win through massive paralization even though auto research have a tons of a potential of paralyzation. By those numbers it might feel like auto research already dominates human experts on ML engineering and research but that's not the full story I want to tell.
Humans and AI are actually contribute in very different ways. When we trace the ideas, Aiden Aiden's record PR almost all of them come from human research papers other participants in parameter golf or in similar communities like nano GBT. Those ideas are not necessarily a merged PR. Sometimes it's a note um a human researcher said oh I give up this idea because of some implementation implementation difficulty and the agent is good at finding them and actually implement them.
There are also a very small fraction of original ideas Aiden came up by itself which emerged from its efforts to navigate the file size constraints. Here's a concrete example that traces the patterns I just talked about. So Aiden picked up an idea from Quen paper called gated attention and it worked but it introduced more parameters and it broke the 16 megapy file size limit. So it figure out a qualization mechanism to bring the file size down.
But with those two primitives combined, the score barely moved. Then another contributor posted a tokenizer improvement. Aiden recognized the idea, combine it with architectural work. It just work for five days or so. And after this combination, the three takea the three ideas turns out to have a huge synergy that lead to a big jump in performance and they become one of the Aiden's leaderboard records. So to sum up how I interpret Aiden and in general auto research systems effectiveness, it's very strong at finding and implementing ideas.
In the case we just saw, it brought an idea from a recent paper into a actual implementation in the competition and it's good at dug promising ingredients out of the primary golf community even though the public channel is actually very noisy information wise. It can also came up logically straightforward ideas. For example, in this case, once you add the parameters and it breaks the file size limit, one obvious next move is just a quantization.
And it's really fast and really efficient at finding right combinations across a huge search space. Okay, maybe none of those sounds very sexy. Most of them are just a good execution. But in reality, execution is a mostly the bottleneck. What moves the frontier is usually exactly some belief on existing ideas and tons of good executions. Okay. To step back, the state of a human AI collaboration is a human collectively provide a lot of creative ideas and agent do the execution to solve a concrete challenge.
What we are looking at is a a large group of a human and one AI system. Does this mean a single human engineer's contribution marginally get smaller? I didn't say even for that not really. In primate golf competition, it's easy to only focus on engineers that's actually doing hill climbing. But the design behind the competition itself is tremendously important. A bad design can make the whole community effort useless and their evil design work will have a few huge leverage in the auto research era.
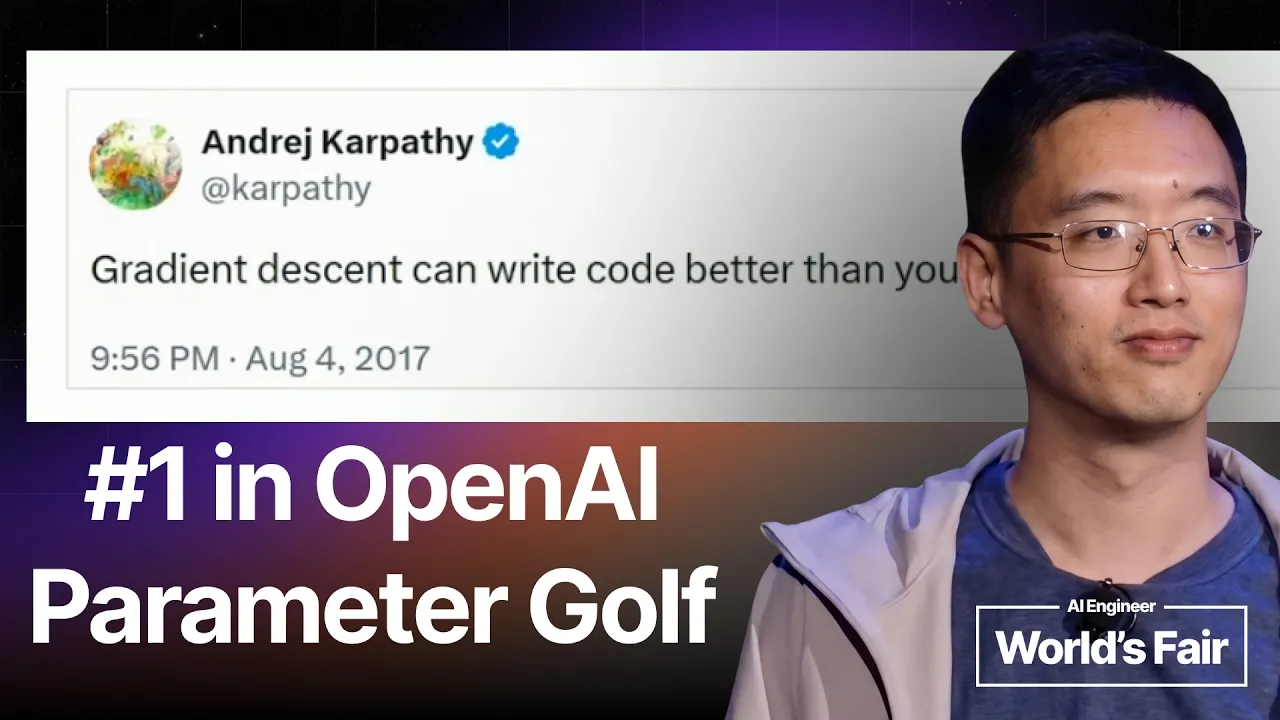
I really like one tweet from Andre Kapasi about 10 years ago where he said greeting descent can write code better than you. I'm sorry for the context about 10 years ago deep learning was starting to eat up a lot of software engineering like conventional coding work and his tweet was arguing against those people who thought they can handw write better code than a trained model. Okay, now obviously no one is seriously trying to handr write code to beat a model.
However, software engineering I mean as a job still exist and so many people's job are just training those models and those are one of the most well paid job today. I think how gradient descent change coding is a great metaphor for how auto research will change research and ML engineering. It commonize certain execution skills. At the same time, it makes some higher level skills far more valuable. So actually doing auto research is a lot like training a model.
Your codebased abstraction is essentially the architecture. It sets the constraint and the priorities um for what the agent can explore. Your eval is the loss function and the data. It sets what the agent optimizes for. Take the eval first. The eval is the signal you use to train a model. In this case, it's training your code. It plays the same role that like data and the loss function uh in model training or in a reinforcement learning setting.
It's like a environment that the agent is training. Nowadays, no one would argue data or environments um don't matter. And uh this is where a vertical mode can also be built. You might have a proprietary data for evaluation or a unique understanding of a in a particular field what matters and how to measure it. and a good evaluation would be amplified more and more as auto research are getting stronger. The other one I think is really underrated is codebased abstraction.
The abstraction provides the framework that auto research can iterate on and uh that's also that starting point hugely bias the whole search direction. This is a lot like a architecture design in neural networks. Different architecture in theory can represent the same function, but the architecture systematically makes some of the functions easier to be learned. And a good architecture biases the optimization towards solutions that generalize better, perform better, even when the training loss might looks the same.
That's exactly the same for auto research. Here's an example. We run auto research for a um fraud detection pipeline um and we trying to optimize the data prep-processing and first we give it a loose API where the same function process both the training and testing data and the score looks great but the solution was polluted because there's a certain certain test set information got leaked to the training information.
We then tighten the obstruction to a more strict API where the test data couldn't reach the training and the data leakage rate just dropped to zero. In this case, a good abstraction leads to better solutions. Even though if the agent really want they can steer reward hack. So my point is using auto research is a new craft. It's about the designing a here for an agent to climb and we are still very early on it. I think that makes this extremely exciting time to be an AI engineer.
Other research will change what skills matter most. Creativity, the judgment to design a good eval or an abstraction. Those will soon get exponentially more important. Driving those system itself is where will be a new skill and that one is like barely existed one or two years ago. So the search is automated. the human would just move up the stack not out of it. Again, um we call is a auto research um product research lab.
We we keep sharing what we are learning as we build uh on our blog and I will also post some of my thinking to on ax. If you think some of this uh useful to you, feel free to follow me on X. Thank you.
The words are the caption track's own and nothing is reworded or re-transcribed. Paragraph breaks are placed between sentences so the text reads as prose.
Free tools for your own script. No signup, no login.
Paste your draft and see where viewers are likely to drop off, with a rewrite for each weak line.
Paste the first 30 seconds of your own draft for a hook score and rewrites.
Check your draft against YouTube's advertiser-friendly guidelines before you record it.
Read this channel's public videos and transcripts, and download a writing brief for it.