Getting the transcript
Reading the captions from YouTube. A video nobody has opened here before takes 10 to 30 seconds; this page fills in on its own.
Getting the transcript
Reading the captions from YouTube. A video nobody has opened here before takes 10 to 30 seconds; this page fills in on its own.
AI Engineer · @aiDotEngineer
This video has no Most replayed graph yet: YouTube shows one only once a video has enough views. These are the moments viewers replayed most in AI Engineer's most watched videos.
Most replayed moment at 11:58
4.6x that video's typical replay level
issues. Uh I also invented OS certification. I just close the tracker whenever I want, so I have my life back. So, does this work? Yes, sort of. >> [laughter] >> Which leads me to act three, slow the down. Everything's broken.
Said at 11:52
Most replayed moment at 18:45
4.8x that video's typical replay level
that they're they're changing they're changing things in the database not yet. You want to run them through the ontology first and make sure that works. Okay. I only got an I've got I've got another I've just a short time. I'm going to try to show you some of the things that um that you can
Said at 18:37
Most replayed moment at 16:13
3.6x that video's typical replay level
method signatures, the program layout and the call stacks. So here's some examples. I don't think you'll be able to read this one, but this is like the level of abstraction we're at. It's how we're actually going to lay this stuff out and how these systems are going to interact. Dylan Mulroy from Cloudflare talks a
Said at 16:06
The graph counts replays. It does not show where viewers stopped watching.
Words
3,397
Runtime
19:15
Speaking pace
176wpm
Reading time
14min
176 words per minute, between the 160 25th percentile and the 181 median of 349 measured videos. That distribution comes from the 349-video hook study.
Opening (first 30 seconds)
[music] Hello everybody. My name is Christopher Lovejoy and I'm a member of technical staff at Anthropic. Uh, and I work as a for deployed engineer. So I embed within enterprise organizations and help them get value from using AI agents. and I previously worked at Anterior with Saul. >> Hi everybody, I'm Saul. I'm VP of engineering at Anterior. We're a New York-based company selling AI uh Aentic AI to US health insurance companies. Um Chris and I have spent a lot of time building in enterprise
88 words, the words spoken in the first 30 seconds at 176 words per minute.
Free, no signup. See how the first 30 seconds hold attention, with rewrites.
Sentence shape
| Measure | This transcript |
|---|---|
| Sentences | 140 |
| Average words per sentence | 24.3 |
| Longest sentence | 211 words |
| Questions asked | 19 |
| Sentences containing a number | 1 |
Most used terms
Filler phrases
124 in total: uh 37 · um 35 · like 15 · kind of 11 · you know 11 · actually 10 · sort of 4 · right? 1.
A literal whole-word count of the same phrase list the Prepublish browser extension uses, so a phrase inside another word is not counted and a phrase used in its ordinary sense still is. It is a count and not a judgement.
What this transcript is
Every word below is the caption track YouTube publishes for this video, pulled from the video itself and reproduced unchanged. It is not Prepublish's writing, not a summary, and not a re-transcription: it is the video's own published captions. English captions, generated automatically by YouTube, in the video’s original language. Source: the video on YouTube. A channel that would rather this page did not exist can ask for its removal through the contact page, and it is removed.
[music] Hello everybody. My name is Christopher Lovejoy and I'm a member of technical staff at Anthropic. Uh, and I work as a for deployed engineer. So I embed within enterprise organizations and help them get value from using AI agents. and I previously worked at Anterior with Saul. >> Hi everybody, I'm Saul. I'm VP of engineering at Anterior. We're a New York-based company selling AI uh Aentic AI to US health insurance companies.
Um Chris and I have spent a lot of time building in enterprise and uh in healthcare enterprises particularly and uh healthcare is a very challenging place to develop and deploy AI. [clears throat] Healthcare is so challenging because of the requirements around uh process and uh compliance the regulatory uh requirements that that that are so important also because of the uh direct real impact that your work has on people's lives which is of course also what makes it so rewarding.
Um I think a lot of the learnings you can take from working in enterprise for healthcare you can take to enterprise in other regulated industries like finance, defense, government work, anywhere where process is so important and has to be followed. And in this talk, we're going to talk about um some of the learnings that we've had and specifically we're going to talk about why enterprise text stacks aren't ready for AI agents and some of the primitives that we've built uh in the past in order to unlock them.
And to make this concrete, let's start by considering a scenario that might be familiar to many of you which is the of enterprise proof of proof of concept, the enterprise PC. And let's say we have identified a customer that we want to serve and we've identified a priority use case with them. So obviously we're on the healthcare track here. Let's consider a um a large health system and a use case that is some sort of administrative healthare workflow.
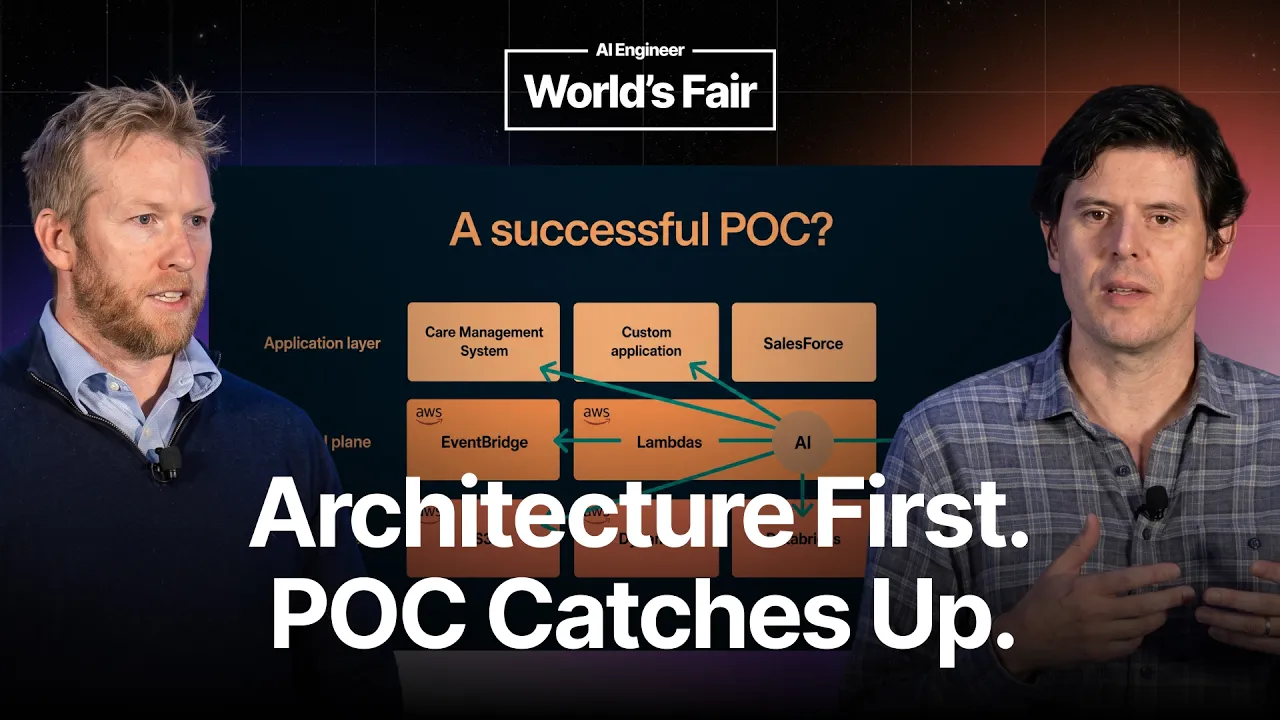
So you work with them, you scope out a PC, you define the metrics that you are going to care about and you're going to bench benchmark yourselves on. Um you allocate to engineers, you spend four weeks building it. And um the actual buildout might look a little bit something like this. >> An enterprise stack is very complicated. It's much much more than we're showing here, but generally you can have an application layer, a control plane layer, the data plane for your PC.
You're going to need some access to the model provider as well. And your PC is going to need access to data across all of these different planes. It may some in the data lake, some directly from the application layer, for example. And so you're going to deploy it something like this. It's going to connect to all these different places. There's going to be some offline data pulling. there's going to be some maybe some online generally you'll get access to the data and push towards the results and so things go well you you get great results the the AI performs you know as you expected you you hit the performance metrics um you know it's fast it's relatively cheap and you hold a meeting you present this to the relevant stakeholders and everyone seems pretty happy um so you know your chief of finance um in the in the company is very excited and wants to understand what's going to be the impact on the budget for next here.
Uh, your chief medical officer is excited to tell his his colleagues, you know, how accurate his AI is. Um, and the head of sales asks, okay, when can we put powered by AI? When can we put that on the websites? Um, but the problem is everyone here is assuming that the the hard part is done, that the AI was was the challenging part, but actually, as we know, often getting things into production is really where the challenge lies.
Um, and to get a bit more specific on what that challenge looks like, um, you hold a meeting the next day. you bring in the relevant stakeholders to discuss productionizing this proof of concept application and somebody raises their hand and says um can I see the the audit trail for this like for us for compliance it's critical that we can see every step every action that the agent takes every piece of data that it accesses can can you give that to me and you realize that actually you know with the way things have been implemented in the initial PC without these um kind of true integrations that actually that's going to be quite challenging and then somebody else um pops up with some other questions so somebody asks okay well actually how is data sensitive data being handled here?
Um how's that being passed to the agency? You know, we have a very strict boundary around where our data can go and where it can't go. Um is is this respecting that? How does that look? And then your chief medical officer says, "Okay, and who's approving the decisions here?" Because we know in certain scenarios we have to escalate to a clinician who will then uh you know approve or or or not agree with what the agent is saying.
Um so how does that happen? Like what's the mechanism for that? And over the course of the meetings you know you can imagine you get more and more questions. So, can untrusted data manipulate the model? How do we know that the agent continues to perform well? How do we deal with integrations? How do we connect to Epic, to Salesforce, to the other kind of applications that we care about? And for the purposes of this talk, we're going to focus on these four, the highlighted ones.
For the other two, feel free to come and chat to me and Sol about these later. We're very happy to talk, but um just in the interest of time, we'll stay focused. And let's start with uh this one about the audit trail. >> So, this is a question you're guaranteed to get from the security team. they're going to want to see an audit trail. And for programmers, an audit trail sounds very like a typical developer log that you might have in Data Dog.
Surely it's it's it's a similar kind of thing. But for security frameworks that exist in the real enterprise world like SOCK 2, High Trust, HIPPA, an audit trail is is a bit more than that. It it has to contain a complete record of absolutely every action that the agent took. It has to contain all of the places where the agent accessed data, all of the authorization by which the agent did something. It's it's this complete record in in a much more fundamental way.
And uh you one way of thinking about it is in a legal sense. It say agents decisions came up in a court of law. Could we show a justifiable chain of evidence for why the particular actions were taken by a decision? And that's something that could easily happen within the healthcare context. For example, when I think about architecting systems like this, I think often about what do I want to make easy? What are when I'm choosing my constraints, I'm saying, okay, these are the things I want my system to be easy and let that drive the tradeoffs that that I'm going to make.
And a particular pattern that uh uh is used in lots of different industries, for example, in finance is a transaction log, an immutable record of events that store all of the transactions that happen throughout the system. And this is appendon timestamp log. It's complete. So this is your source of truth for all of the data of the system. And it's unified. So there is only one source of truth across all of the different agents that you might have running in parallel for example and architecting in this way making this trade-off uh means that auditability becomes trivial.
It falls out of your data storage paradigm that you've chosen. It's sort of it's impossible not to be able to roll back time and and see exactly the state of the system at a a particular point in time and be able to uh provide that as an audit trail for what happened uh at at each point in time. And of course these are trade-offs. So what's the trade-off you're making here? I think we could say that for uh this kind of event logging or sometimes called event sourcing pattern writes become very easy.
So you just drop an event. reads become more difficult because you have to uh read through all of the events in order to reconstruct a view of what happened and there are patterns like caching and snapshots that you can bring to to to make that that simpler but there always is more effort there although I have seen in in the healthcare context that actually you're going to want different interpretations of the raw data that your agents recorded after the fact.
So for example, it might be that uh more events happened and that changes the interpretation of the healthcare journey and you want a different view of this the source of truth at that particular time and this pattern makes that easy because uh all of your views of the data are ephemeral computed projections of the event log. Um okay next the compliance officer comes and is asking how is the sensitive data passed around the system what's the life cycle of data within our system and within a healthcare context as we all know data means a lot it's PHI protected or personal health information it's uh has legal restrictions around it not just HIPPA but other legal restrictions about the use of people's data you cannot have your agent Just as you cannot have humans accessing and reading and utilizing healthcare data that they don't absolutely have a necessity to use at at that point in time for that particular uh journey and so again architecturally when I think about how am I storing data within a particular system I would like to think what is the shape of the data what kind of characteristics does the data have for healthcare data that might be that it's very complicated It doesn't follow strict hierarchical um relationships.
It's uh sometimes unstructured and it's sometimes structured. It could be very large. For example, healthcare data, one piece of healthcare data can easily be over a megabyte in size or or much more than that. Uh it has strict access controls as we've been saying. The rback comes into play like uh both for humans and and then for agents downstream of that. Uh it may even be we I've seen customers where they're not willing to have their healthcare data leave their own environment, leave their on-rem VPC for example.
So we have tangential access to their to their data. And so an architectural paradigm I might go to is object storage. Schemadriven object storage I think is a good fit for this. It's matches well with the choice of using event logging because you can separate the two. So the events we talked about as the record of what the agent is doing at any particular time only contain references to the schemadriven blobs that are the storage of the actual healthcare data itself.
And uh it's important therefore that the healthcare data is stored immutably again so that you can always go back in time and reconstruct what data the agent had access to at that particular point in time. This separation of events for what happened and object storage for the data that was used at that particular point in time has actually some some very useful benefits. For example, with a system like this, it's possible for developers to go back and debug and have observability over what happened, what particular steps the agent took, why it did that, and and retrace the agent's steps without having access to the personal health information itself.
Although because of the schema driven, they can see the shape of that data, they they can't and to be honest, often won't be able to be given access to that healthcare data. So you can separate out observability and orchestration and instrumentation from the healthcare data itself. This then has another benefit which is zero trust. It it the object storage becomes a place where you can apply zero trust principles. Your agents can bear tokens and use those tokens to access the data at the point of use and not allow data to flow around the system as it likes.
This then leads into a mitigation for uh prompt injection for the lethal trifecta. The way I think about the lethal trifecta is can I solve for the constraint if I have an agent at point A with access to this data. Is it possible within my architecture for the agent to be also accessing data over here? And zero trust principles, tokens beared by the agents and object storage segregated from the uh event stream that has your orchestration logic gives you a place to be able to solve for that constraint.
It won't be possible for the agent to access data within the same process that that you've given it the the previous data. >> Okay. Okay, so then it comes to how do you handle escalation? And in many scenarios, you will want to be able to escalate a decision that an agent makes or an action that an agent makes to a human. But one of the challenges here is that this is quite dynamic. So you don't know in advance when exactly perhaps the agent's going to escalate.
It could be that you're asking the AI to escalate when it's not sure. Um it could be that you define some sort of rules in your system. Maybe in a medical context the treatments going above a certain threshold means that it needs to be escalated uh for an approval. [snorts] But this makes it very challenging um because of this this inability to predict. And a second challenge is also that humans and LMS ultimately process context differently.
You know LM will have no problem if you give them massive massive amounts of text but humans um that's not the case. So what we've seen is that one pattern that can work very well here is if in your platform you enforce kind of a wider definition of agent which encompasses both LLMs and humans then you can make it such that any action that can be taken by an LLM could also be taken by a human and this is helpful because at any point in the kind of chain of actions that your agent is taking it can escalate to a human. the human could perform that action and then any step downstream doesn't care about whether it was a human or an LM that did those actions upstream.
Um and on the second point around the context, what this also uh makes much easier is that you can define methods that take the context which has some kind of shared definition of context which is irrespective of whether it's a human or an LM that's going to be accessing it and you can take those methods to then map into something that's agent friendly like a prompt or into something that's more human friendly for example a UI.
Okay. And then on this fourth and final question that we're going to talk about um eval obviously you know we hear a lot about evals we know that evals can be very helpful that often they drive decision-m about the types of model you want to use the type of approach you might want to use um within your product but we also know that evals can be pretty hard and there's various factors here we [snorts] know that LLMs are not deterministic so it can be quite tricky to pin down the precise change that led to some sort of change in output um we also know that the data that you might put in an offline data set might not necessarily represent production data and it could be that um maybe you sampled from data but actually that sample isn't truly representative and then you also have drift of data um over time so maybe your offline data set is now out of date and what we found is that these three primitives that we've described described so far in the talk actually give you effective privacy preserving evals almost as a byproduct um without needing to kind of bolt something onto the side of of your um architecture.
So to make that more concrete, so the immutable ledger, what this means is that you can replay your actions. So you can go back to any particular time, you know, in this kind of sequence of events, you can see the complete state of the system at that point in time. And if you wanted to, you could then make very specific tweaks. So you could tweak a prompt, you could tweak a model, you could tweak the code, and you can see the exact direct impact of that because you have all of that context.
Secondly, you have this human agent equivalency which means that for any task you could get both the agent, the LLM agent and the human to perform it and your difference is your eval that gives you the eval scores. And then finally, what the object storage enables you to do is to actually run these evals on production data um including inside your customer's environment without actually ever exposing that data. and you can get your eval results without the sensitive data ever needing to come to where your agent's performing the work.
Right? So, we've gone through four architectural principles that we found useful for building in healthcare and more generally in regulated environments for enterprise. the immutable ledger of actions, the orchestration adjacent object storage, the human agent equivalency and the way that with these three principles eval can emerge as a first class property of the system rather than as something you attach onto the side.
I think one of the metas here is that I like to think about architecture as taking your constraints very seriously and thinking about what you want to be simple within the system and then choosing the trade-offs for that. And of course alongside that some things will become hard but it's the things that are simple that are most important to you. And that there are patterns that already exist across enterprises that solve for a lot of these things.
And sure with AI we need to combine them in new sometimes radical ways and bring in other way other pieces but there are patterns that have worked very well within finance within defense within big tech that that can be applied to this kind of system architecture and I'd say the takeaway is that where I've seen it go wrong is taking that initial P that um that point solution that showed so much promise and that that showed the high accuracy for example and then trying to build up from it, strapping on the enterprise requirements as you come across them.
Okay, we need evals, we need uh security, we need auditability and bolting these on as additions to the the the foundations of the PC. You end up with something very brittle, something very hard to uh uh externalize and to generalize across different use cases. But where I've seen it go well is if you take the constraints of a productionready scaled enterprise uh system seriously from the beginning and treat those as the architectural principles that you're going to build everything upon and then build back up towards that PC accuracy using your new primitives.
Thank you for your attention. Thank you. [applause]
The words are the caption track's own and nothing is reworded or re-transcribed. Paragraph breaks are placed between sentences so the text reads as prose.
Free tools for your own script. No signup, no login.
Paste your draft and see where viewers are likely to drop off, with a rewrite for each weak line.
Paste the first 30 seconds of your own draft for a hook score and rewrites.
Check your draft against YouTube's advertiser-friendly guidelines before you record it.
Read this channel's public videos and transcripts, and download a writing brief for it.