Getting the transcript
Reading the captions from YouTube. A video nobody has opened here before takes 10 to 30 seconds; this page fills in on its own.
Getting the transcript
Reading the captions from YouTube. A video nobody has opened here before takes 10 to 30 seconds; this page fills in on its own.
Theo - t3․gg · @t3dotgg
This video has no Most replayed graph yet: YouTube shows one only once a video has enough views. These are the moments viewers replayed most in Theo - t3․gg's most watched videos.
Most replayed moment at 2:36
5.6x that video's typical replay level
Well, you have nothing to worry about cuz the first million users are free. Get yourself enterprise ready at soidiv.link/workos. I'm very excited to read into what Linear is cooking here. You know they're cooking something different cuz this is the only not dark mode page I've ever seen Linear ship. They actually took
Said at 2:29
Most replayed moment at 25:09
3.4x that video's typical replay level
just set up now. It's really nice when you do need to do things in the GUI or format the machine, that type of thing. It's time to show you guys how I actually do work using this setup. NPX T3 at nightly serve. I do have these host commands to make it work better
Said at 25:02
Most replayed moment at 2:53
29.0x that video's typical replay level
of different places in order to pull it together. Setup couldn't be easier. You click start, you add a new database, you get a connection string and now you're good to go with a real Postgress database with all the power of ClickHouse behind it. Stop compromising on your database today at soy.link/clickhouse. The best
Said at 2:45
The graph counts replays. It does not show where viewers stopped watching.
Words
4,998
Runtime
25:27
Speaking pace
196wpm
Reading time
21min
196 words per minute, between the 181 median and the 201 75th percentile of 349 measured videos. That distribution comes from the 349-video hook study.
Opening (first 30 seconds)
Nvidia's a weird company. They originally started making chips for gamers to have fancy 3D graphics in their computer games, and now they are the most valuable company in the world powering the majority of intelligence that we get from all the fancy AI tools we use every single day. There's a lot of pieces that make Nvidia's borderline monopoly on compute for intelligence just impossible to crack. Things like CUDA, which is the language and system of choice for the vast majority of AI research, to the crazy deals that they're cutting with everybody from the government
98 words, the words spoken in the first 30 seconds at 196 words per minute.
Free, no signup. See how the first 30 seconds hold attention, with rewrites.
Sentence shape
| Measure | This transcript |
|---|---|
| Sentences | 311 |
| Average words per sentence | 16.1 |
| Longest sentence | 71 words |
| Questions asked | 10 |
| Sentences containing a number | 63 |
Most used terms
Filler phrases
49 in total: like 24 · actually 10 · you know 4 · kind of 3 · um 3 · basically 2 · literally 2 · uh 1.
A literal whole-word count of the same phrase list the Prepublish browser extension uses, so a phrase inside another word is not counted and a phrase used in its ordinary sense still is. It is a count and not a judgement.
Free, no account. See where attention is likely to drop, with a rewrite for each weak line. The free check shows the scores and the one issue costing the most. Or run it on the words above first.
Free · No login · See a sample audit first if you prefer.
What this transcript is
Every word below is the caption track YouTube publishes for this video, pulled from the video itself and reproduced unchanged. It is not Prepublish's writing, not a summary, and not a re-transcription: it is the video's own published captions. English captions, generated automatically by YouTube, in the video’s original language. Source: the video on YouTube. A channel that would rather this page did not exist can ask for its removal through the contact page, and it is removed.
Nvidia's a weird company. They originally started making chips for gamers to have fancy 3D graphics in their computer games, and now they are the most valuable company in the world powering the majority of intelligence that we get from all the fancy AI tools we use every single day. There's a lot of pieces that make Nvidia's borderline monopoly on compute for intelligence just impossible to crack. Things like CUDA, which is the language and system of choice for the vast majority of AI research, to the crazy deals that they're cutting with everybody from the government itself in the United States to businesses like of course OpenAI, Anthropic, XAI, and more.
And it seems like everyone is realizing that Nvidia is a not great core dependency to have on your business's success. OpenAI could not function if Nvidia decided they wanted to start charging them 10 times more. The US government would be pissed if their whole plan to build this crazy set of data centers fails because Nvidia changes their mind. A whole of these businesses are struggling to work with the terms Nvidia's giving them today.
And with the promise that those terms will get worse tomorrow, they're all looking for ways out. But there's one particular place that is more motivated than anywhere else to solve this. China. Nvidia chips have largely been banned from being sent to China by the US government. Some have been cleared for export, but it's a very very small set, and it's not the giant powerful GPUs that we are using for training in the US.
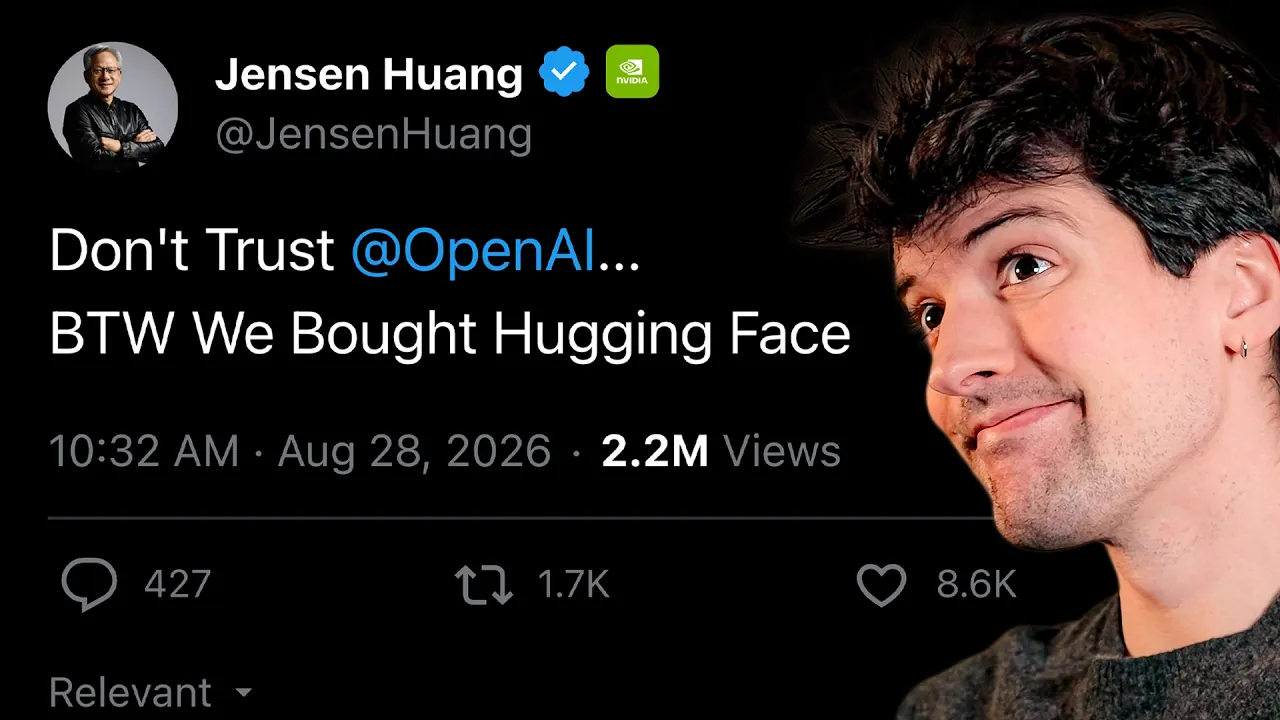
All of this is pretty much forced the Chinese labs like ZAI to rely heavily on chips that are being made by Chinese companies like Huawei. But it's not even just the Chinese labs anymore. Even OpenAI has started developing their own chips to get faster, cheaper inference and training available to them internally. All of this has Nvidia acting pretty scared and very very weird. From crashing out on Jim Cramer's show to buying Hugging Face, a little bit absurd.
But as you guys can probably guess, I have a lot of thoughts on this. I'm a big nerd about chips. I'm a big nerd about Nvidia in particular, and never been the biggest fan of them. And the opportunity to point out how their monopoly is about to be crushed and crumbled is one I have to take. But unlike my friends who invested in Nvidia early, I don't have billions of dollars to spare, so I'm going to have to take a quick break for today's sponsor.
I got a hot take for you guys. The knowledge in existing LLMs is nowhere near enough for us to do real work and get our jobs done. Thankfully, the labs have noticed this, too, and that's why the majority of the context your agents work with isn't stuff that they already knew, it's stuff that they got from the internet. The vast majority of the context in our real context windows is things that the agents fetched from online.
What I'm trying to say is that your agents need access to the internet, and if they want the best possible way to do it, you should probably use today's sponsor, Browserbase. They provide all of the pieces your agents need to be smarter and have modern knowledge. From their search API, which is literally a single curl request that allows your agents to look things up and find real context from the web, to their fetch API, which lets agents give a URL to Browserbase and get back markdown that can actually parse and understand from pretty much any website across the entire web.
And don't forget about the browser as a service, which allows your agents to actually navigate the web like a human would with a real Chromium browser, allowing them to fill out forms, sign into pages, and do real actions on users' behalfs. Over 85% of the APIs on the web can't be accessed by simply curling them. If you're okay with only having that 15%, stick to curl. But if you want to unblock your agents and give them the whole web, do it today at soda.link/browserbase.
Before we can talk about how Nvidia loses, it's important to understand how they won. There are a couple core pieces, but I want to just fixate on the two that I'm most interested in right now. Those pieces are, of course, the chips that are being used by all of these companies that Nvidia makes. But the other piece is CUDA. We'll come back to this one in a bit because this is where things will get complicated. But for now, I want to focus on the chips side.
GPUs are uniquely tailored for these types of AI tasks because they have millions of small cores instead of a handful of big ones. In order to traverse these gigantic piles of weights and parameters that a model is, you have to trail all of the data inside of it to make a response. You get a lot of value from having a chip that has lots of different processors on it that can handle that type of large amounts of data and crazy matrix transform [ __ ] Lots of small brains are a lot more powerful than one giant one in these cases.
You also need to have enough memory to hold the weights that are being traversed, which is another real fun problem that Nvidia is consistently causing for themselves. The two pieces of a given I'll change this to be GPUs. The two pieces that matter for a GPU are the actual like process itself. I'll say the chip and the high-bandwidth memory are probably the easiest way to do this. The GPU has these two parts. The actual silicon that has all of the things on it that can process all of this data and then the high-bandwidth memory, which actually holds said data.
Nvidia has had a lot of fun with this split and arguably using it to fix prices in their favor. I won't say it's cheap, but getting a powerful Nvidia chip is not the hardest or most expensive thing in the world. One of the highest-end Nvidia GPUs available in terms of its actual like GPU performance and throughput is the RTX 5090. The retail price for the RTX 5090 was originally $2,000. They now consistently go for around 4,500 because the demand is so absurd.
There's also a server card they put out called the RTX Pro 6000 that ranges between 12,000 and $16,000. You would assume this chip must be way, way faster than the 5090 if it's going to be six to 10 times more expensive. But guess what? It is the same speed or slower. This might sound crazy. You might be confused. How is the chip that costs six to eight times more slower? Why would I ever get that instead of the 5090?
Well, it turns out the chip isn't the only thing that matters. The 96 gigs of GDDR7 are what mattered here. The 5090 only gets 32 gigs of GDDR7 and it's not error correcting. Technically, the RTX Pro has more CUDA cores, but I believe the process on the 5090 is slightly like newer and better. It should be within spitting distance for the raw performance and throughput there, but the RAM difference is why they're able to charge so much more.
And just to be explicitly clear here, they were doing this way before RAM got more expensive. They do this because they know the people who need a fast chip and a lot of RAM are much more willing to spend lots of money than a video game player is. And we're already seeing my favorite question in chat, which is why not just connect them? I'm going to use my favorite analogy I always use for chip-related stuff here. A kitchen.
Imagine you have a kitchen that serves a bunch of customers at your restaurant. You have three really talented chefs in there, but your freezer is full and your refrigerator is full. You're running out of space. So, you decide you need another fridge. You're out of space in your restaurant though, but you need that other fridge pretty bad. So, you buy a building a mile away and you put the fridge there. Maybe you put 10 fridges and five giant deep freezers there.
You massively increase the amount of storage you have, but now every time the chef needs something from those fridges or freezers, they have to run a mile to the other place, grab it, and then run back. You can't just plug the chips in together. If you have a model that is 40 gigs, hell, if you have a model that's 33 gigs and it doesn't fit on your 5090, you now have to split the data across the two GPUs, which means ideally you have some way of predicting which data is needed when and how so that GPU one only has the data it needs and two only needs the data that it needs.
Good luck. Have fun. Not [ __ ] happening. There are techniques around things like mixture of experts models that allow you to more easily some amount assign the work across stuff. But there is no way on consumer hardware to get reasonable bandwidth between two 5090s to allow them to share memory. By the way, that memory that they're using for this is as much as 48 gigabits per second. That means you need something even faster in order to transfer the data between the GPUs.
Once again, not happening. Don't worry though, Nvidia has an answer for you. If you need more memory, they're more than willing to sell you something. And no, I'm not referring to the RTX Pro. They know that there are people who can't put out 18 grand plus on a GPU that they're just going to use to run shitty models locally. And that's why they made the DGX Spark. This small little box costs four grand and I hope you don't plan to use it as a computer.
That is what it is to be clear. It's a computer. It shows up running a botched install of Ubuntu that they filled with [ __ ] and it runs a 20 core arm chip. And having spent far far far too much time fighting arm Linux in my life, I promise you you're not going to use this computer as a computer. Linux on arm is hell. Don't bother for this for anything other than inference. So this arm chip in this random $4,000 mini PC that you can't use as a computer does have a benefit. 128 gigs of unified memory.
That memory is LPDDR5 memory though, which says a different number here. There's a lot of layers to how those numbers are measured. LPDDR5 is meaningfully slower than GDDR7. So the RAM is slower, but you have way more of it. But most importantly, you have CUDA cores, cores that can be used with CUDA-backed stuff that are actually capable of running real workflows. But you get 6,000 of them instead of the 24,000 plus you get on hardware like a 5090 or an RTX Pro.
So, your options here are the world's worst computer environment possibly that you can buy today for real amounts of money. But you get a real amount of RAM you can use for models at the cost of an absolute [ __ ] garbage chip that runs terribly slow. Or you can get a really powerful, capable chip like an RTX 5090, and now you're entirely gimped on RAM. And if you want RAM and a high-end chip, you're paying the 16,000 plus dollars for that RTX Pro, sadly.
Do you see what they've done here? They have the cheap option if you need more RAM. They have the cheap option if you want a fast chip. But you're paying up to 10 times plus more if you need both. They did do one really nice thing with the Sparks. They gave them a 200 gigabit per second NIC so that you can connect them over SFP. So, you can have the different Sparks transfer data between each other relatively fast. It's hell to set up, but you can at least do it.
So, we've addressed all the fun things here for where Nvidia's at and how they can charge these absurd prices. What we haven't yet addressed is why I'm filming this today. There's a couple of things that are inspiring me to take this video on. The first is an anonymous model that dropped last week called Aux Alpha. I already have a video about this. It's probably already out on the channel, by the way. You should check that out.
And when you're on the way to it, you should hit that subscribe button cuz it costs you nothing and with these videos take a lot of work. So, Aux Alpha was an anonymous model that came out on open router and open code, both of which had an absurd amount of free throughput on them. I believe it was 100 trillion tokens a day for free. And the model was great. A bunch of people were using it. I was using it a bunch. I have a video about how much I love it.
Great model. Turned out to be GLM 53 flash. And the reason they could serve it so aggressively is both because it's a relatively small model, but also because they served it entirely on Chinese chips. Huawei made the chips that they served all this traffic on, and it's still working great. It's genuinely impressive that without any Nvidia in their stack, they were able to do this absurd level of traffic. I also got called out here because people were saying only Frontier Labs have this much compute.
When I said that, I assumed that they were still serving Nvidia because we basically expected that. And also this wasn't a small model. To be fair, when I tweeted that, my secret personal belief was that Xiaomi was doing this on Chinese chips somehow. Then it turned out to be GLM shipping again in like a 2-week window, also on those same chips. All of the traffic was served on Chinese chips attaining hardware efficiency and per token cost comparable to Nvidia GPUs.
The CUDA mode is being tested once again after Jalapeno's announcement yesterday. Jalapeno's Open AI chip that they've been working on in order to get out of the hell of relying on Nvidia so much. They are partnering with Cerebrus, who's a company that makes faster inference chips and host models that way in order to everything they can to massively increase speeds and reduce costs. But that is not the only thing that was just announced to scare Nvidia.
Apple, out of nowhere, announced upgrades to the Mac mini, but more importantly, the Mac Studio, which has not seen upgrade since the M3 era. And the M4 did kind of come out, but they never made an M4 Ultra, they only made an M4 Max and it was gimped on how much RAM it could have. So you were stuck with like a 3 and a half plus year old chip if you wanted a lot of RAM on a Mac Studio. Obnoxious, dumb, solved. The Mac Studio now has M5 Max and Ultra.
The first section here is for the Max, which you have 128 gigs of RAM and 614 gigabytes per second of memory bandwidth. But the Ultra is basically just two of these chips stapled to each other, which means it can do 36 cores of CPU, 80 cores of GPU, up to 512 gigs of memory, 1.2 terabytes a second of bandwidth, and a 32 core neural engine. As a video nerd, I love the fact that the new Ultra chip can do 33 streams of 8K ProRes 422 at 30 FPS playback.
Like that's insane. But that's not what we're here for, let's be real. We're here because the time to first token on a Mac Studio with M5 Ultra is 10 times faster than it was on a Mac Studio with M1 Ultra. That is a massive increase in performance and this largely comes down to the improvements in the memory. But the important thing to note here with the memory isn't even just the amount, it's this word here, unified.
Because that means it works as normal RAM, but also as VRAM, which means the GPUs can use it for inference. When you look at the Mac Studio compared to Nvidia's options, you see just how compelling it gets. You can get a 590 which has crazy GPU performance, which isn't indicated here how fast the computer is on it. You only get 32 gigs of RAM though at the benefit of the way Nvidia implements it, effective 1800 GB per second memory bandwidth.
The RTX Pro, similar bandwidth, 3x the RAM, much more than 3x the price. The DGX Spark, way more RAM up to 128 gigs, but it's unified LPDDR5, that is a seventh or so the speed, but suddenly we get a thing with no compromises. No compromise on the amount of RAM, no compromise on the memory bandwidth, and depending on how it performs when it comes out, not as big of a compromise on the compute itself. So for 10 grand MSRP and the current price still that cuz it isn't coming out soon, you get way more RAM than any other option as offered by Nvidia, a chip that is meaningfully better than the DGX Spark, comically so even.
Not necessarily better than the GPUs in the 5090 and the 6000 Blackwell. We don't know yet until it's actually out, but I'm guessing almost certainly not. But most importantly, you get 256 gigs of their unified memory with bandwidth a hell of a lot closer to what Nvidia sees on their GPUs than to what that you would get on a Spark. Almost six times faster than the Spark and only like 30 to 40% slower than the 5090. That is insane.
This kills almost all of the reasons you could ever justify buying the DGX Spark, which is a whole category of Nvidia devices killed. And all the people who upgraded from a Spark to a RTX Pro 6000 or skipped the Spark because they wanted speeds that weren't trash, they can now get way, way better experiences for meaningfully cheaper by just getting the M5 Ultra instead. That's crazy. This is Apple's first real play in the AI space.
Them coming in and saying, "Sorry guys, you're [ __ ] around too much. We're going to put an end to that." And yes, the DGX Spark's effective memory bandwidth is actually this pathetic. It's a [ __ ] chip. It's a [ __ ] system. The DGX Spark is my least favorite computer in this apartment. What about Jalapeno? Well, according to SemiAnalysis, it is coming out to be better than Blackwell. Their self-designed ASIC comparing with Rubin, which is Jalapeno's TCO through per megawatt and spicy deeds.
Cool. Open AI actually invited SemiAnalysis come take a look early. In general, first energy and trips are not competitive, but Open AI bucks that trend by being industry leading and beating every Nvidia, AMD, and Google chip we have been able to test on multiple top open source models. Open AI does this with extreme hardware software code design. Traditionally, these bespoke chips tend to super fixated specialize on specific things.
They have not actually done that. They built a really good general chip that delivers high performance in all scenarios. Apparently, their chip goes as high as 216 GB of HBM, they only require 700 W, and it's doing 13.4 petaflops for FP4. And yeah, those are insane numbers. Apparently, it doesn't have FP16 numbers, but for FP8, it is slightly behind what you're seeing on GB2000 and 3000s from Nvidia, but it's meaningfully ahead of the H100 and 200 already, which is pretty crazy.
And also, more RAM and way higher bandwidth. Even just this chart should be enough to give Nvidia a heart attack. It's still not quite Reuben levels, but it's trading blows at a way lower wattage. A lot of the media coverage of this chip has followed a few throwaway comments from OpenAI that claim the chip will be optimized for their models in a way that other chips aren't. This is wrong. Jalapeno is a generalized inference chip capable of running all sorts of models in all sorts of workloads, including our benchmark inference X, where we ran the benchmark with OpenAI engineers in the lab.
As a joke, OpenAI even showed us it running Doom, which was ported to their chip with just Codex prompts. Of course, they have it running Doom. The following is the headline performance per watt result. So, let's see what the numbers looked like. It's looking pretty insane token per second per megawatt performance here. They are crushing everything else in efficiency in terms of electricity. Jalapeno is beating Black Hole on performance per watt across almost all scenarios without being tuned for any specific point in the curve.
It excels not only at low latency scenarios, but also in high throughput scenarios. A more apples-to-apples comparison is against single token prediction results. It knocks every competitor out of the water. At low concurrency scenarios, Jalapeno demonstrates remarkable interactivity, hitting over 700 TPS per user at concurrency one on the DeepSeek R1 model. This is all being achieved with single token prediction, no speculative decoding, and no prefilled decode disaggregation.
They got Kim 25 and GPT-OSS running at 1400 tokens per second per user. And they confirmed that the GSM-8KE valves attained results on par with Nvidia chips, so So, not nerfing the models when they run them. Since they're using HBM4, which is the new generation of high-bandwidth memory, they get a pretty substantial win over things on older memory. Rubin is the new Nvidia line that will use HBM4, but those chips are not really actually out yet.
Blackwell is the line that most things are buying and using. There are people who have put in huge orders for Blackwell chips that will finally show up in like 2 to 3 years. It's a while before Rubin's going to matter. There's also the callout that this is not large model performance. All the models they've tested so far are relatively easy to run in terms of size. So, we don't know how these will perform when you give them huge models like Kimmy K3 or Deep Seek before Pro.
OpenAI is designing for performance per watt. The reason is simple. OpenAI is currently limited by data center power, not by budget or floor space, and thus tokens per megawatt is paramount. At Computex 2026, Jensen said the performance per watt, reliability, and long lifetimes are the core features of future GPUs. To quote, "If you have 1 gigawatt of power, then throughput per watt is revenue." Yep. I've been yelling this for a while.
Electricity's going to be a big deal. So, OpenAI focusing on that side is a huge deal. Don't worry though, Jensen's definitely not scared. Nvidia has a plan. They're going to be totally fine. Not like he's going to say something stupid like they're just going to cancel the development of the thing that destroys our business model. I haven't actually seen this clip, so we get to watch it together. >> And I said, "You know what?
I The whole time I've been working on on something, a chip that I think could really hurt you. It's called jalapeno. I don't know what let's call it I don't know what something to call and you said to me, "Well, that's fine." Would you really say that's fine cuz I personally would be hurt if OpenAI did to what they do to Nvidia if they did to me. >> You know, I'm okay with it, Jim. There's so many XPUs that are being announced, and as we know, it's not easy doing what we do.
We've been doing this for 33 years. And so, lots of projects get started, a lots of projects get gets canceled. Um we're we're here we're here to support our partners and and um, we're going to build the world's best technology. I have every confidence in that. Uh, we're going to be the most productive infrastructure that they have. I have every confidence in that. Um, we have the supply chain and the technology scale to be their largest supplier.
I have every confidence in that. And so, you know, I I don't I don't have to take anything personally because I've got so much confidence in what we we're able to deliver. And look at look at all of the XPU announcements and all the startups that have been announced and yet today Nvidia is increasing our market share of the AI market. We're our growth is accelerating. Our technology leadership is extending. And so, I'm very comfortable with all the competition. >> Okay, and I also >> Yeah.
Definitely not scared at all, are you, bud? Well, on the bright side, if they own Hugging Face, they can make sure they suppress access to all of the versions of the models that run well on things that aren't CUDA. I'll say that I think the Hugging Face bid is an actual good faith play to try and bolster and fund the development of open source AI and encouraging more and more people to train because let's be real, training is still happening on CUDA.
The more they encourage businesses to try and train and fine-tune and customize things themselves, the more customers they have for their chips, the longer-term their absurd saturation can go for. And Nvidia's still making a ton of money. They can justify doing [ __ ] like this. Good for them. If you want to spend less than $12.9 billion to do something that positions your business better, you have access to my DMs, Jensen.
Somebody in chat mentioned, "You know what's funny, Theo? I bet SpaceX AI is also doing something similar now." Which reminded me, somehow I entirely forgot about Terafab, the most epic chip building effort ever, which is, by the way, the only thing in Elon Musk's bio right now, despite the fact that him and Jensen are buddy-buddy and Elon has some of the biggest and most lucrative contracts with Nvidia. He has more GPUs than Anthropic does.
Anthropic is renting GPUs from Elon now because he was so quick on this. And he is still concerned about Nvidia's monopoly and just trying to get out of it. Terafab will close the gap between today's chip production and the future's demand, a future among the stars. And we do this by building a gigantic chip fab. The Terafab will be comically bigger than even giant things like the Giga Texas fab for Tesla, the US Pentagon, Mall of America, and more.
It's 25 times the size of Apple Park. It's 20 times the size of the Pentagon. Kind of crazy. So, yeah. I guess you could say Elon and SpaceX AI and Tesla or whatever whatever business he has doing this are considering competing with Nvidia. It's almost like literally everyone is. I should include a callout here. I am an AMD investor. I am not a special early investor. I'm just buying their stocks, but I have not talked about AMD at any point here cuz I'll be real.
I love them to death. They're very behind. It'll be a while before they can catch up to what these other things are that I'm talking about here. I hope that changes, but for now AMD is a potential big winner, but they have some time to before they get there. I think that's all I have to say on the chaos that is the current state of chips. Apparently, Intel is involved in Terafab, too. Fun. That'll be an interesting project.
I have no idea where any of this will go. All I know is that Nvidia is scared, and they have good reason to be. The AI world constantly is changing, and these tools and technologies make it easier than ever to catch up. We finally now have models that are useful enough to help these manufacturers in their process. I think this is a big part of why OpenAI is catching up as quickly as they are. Their use of AI in their catch-up process has enabled them to do it more effectively than anyone would have anticipated, including Nvidia.
And now we're quickly approaching a future where the labs are able to compete with Nvidia directly instead of relying on them with these trillion dollar contracts to get all of the chips they need. As I've said many times now, the future is going to be fought not on chips, but on electricity. And if we don't have ways to get the energy we need, then none of this ends up mattering in the end. But at the very least for now, it is super interesting and Nvidia's weird position in the market might not last as long as they probably think.
Am I crazy for saying all of this or am I kind of onto something? Let me know how you guys feel about the future for Nvidia and this whole space in general in the comments. Until next time, peace nerds.
The words are the caption track's own and nothing is reworded or re-transcribed. Paragraph breaks are placed between sentences so the text reads as prose.
Free tools for your own script: paste a draft and see where it stands before you record it.
Paste your draft and see where viewers are likely to drop off, with a rewrite for each weak line.
Paste the first 30 seconds of your own draft for a hook score and rewrites.
Check your draft against YouTube's advertiser-friendly guidelines before you record it.
Read this channel's public videos and transcripts, and download a writing brief for it.